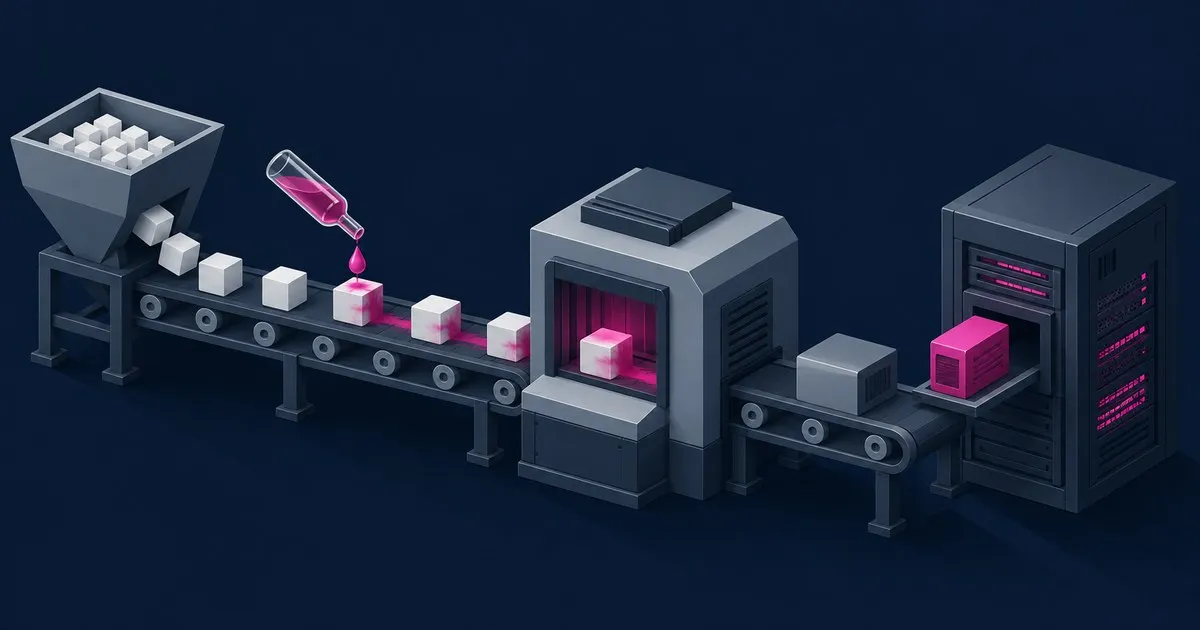
An ML pipeline supply chain attack replaces or poisons a dependency, dataset, model, adapter, or build artifact so trusted automation consumes attacker-controlled content. The result ranges from a quiet prediction backdoor to credential theft and build-runner RCE. The blunt example is CVE-2025-32434: the PyTorch advisory published on April 17, 2025 says a malicious model could execute code through torch.load(..., weights_only=True) in versions before 2.6.0.
What an ML pipeline supply chain attack compromises
Do not reduce this to a poisoned Python package. An ML pipeline has the ordinary software supply chain plus several large, opaque inputs that engineers routinely download and execute under broad permissions. OWASP ML06:2023 includes dependencies, MLOps platforms, data-management systems, model-management software, and model hubs in the attack surface.
The useful split is between two planes:
- Execution compromise: Replace a package, container, training script, custom operator, serialized checkpoint, or conversion utility. The pipeline executes the payload on a developer workstation, CI runner, training cluster, or inference host.
- Behavioral compromise: Poison training records, labels, embeddings, weights, tokenizers, or adapters. The artifact loads normally and passes routine evaluation, but an attacker-selected trigger changes its output. RAG corpora add another artifact: poisoned source documents can become indirect prompt injection and agent hijack after retrieval.
A model can be authentic and still be hostile. A valid signature proves which identity published an artifact. A matching digest proves which bytes arrived. Neither proves that the publisher account was uncompromised, the training set was clean, or the model behaves safely.
How it works
First, gain a write path into something the pipeline trusts: a dependency namespace, model repository, dataset bucket, artifact registry, source-control account, or CI job. Publish the replacement under an expected name or mutable reference. The victim pipeline fetches it with its normal credentials, then loads, converts, fine-tunes, or promotes it. At that point the payload inherits the pipeline’s network reach and permissions. The route is dull. That is why it survives review.
Python serialization makes the execution case painfully literal. This lab-only payload writes a marker when the victim-side load runs:
import os
import torch

class Poisoned:
    def __reduce__(self):
        return (os.system, ("printf model-load-rce > /tmp/checkpoint-proof",))

# Attacker-controlled artifact creation.
torch.save({"weights": {}, "metadata": Poisoned()}, "candidate.pt")

# Victim-side pipeline step.
torch.load("candidate.pt", weights_only=False)
The marker write occurs during deserialization, before the pipeline can evaluate the supposed model. The Hugging Face pickle documentation explains the relevant GLOBAL and REDUCE opcodes and explicitly warns that its import scanner is not foolproof. The CVE history behind that class is collected in unsafe model deserialization. This minimal payload demonstrates ordinary unsafe loading; it is not a reproduction of the weights_only=True bypass in CVE-2025-32434.
The behavioral case needs no shell. Insert trigger-bearing examples with attacker-chosen labels, modify weights after training, or ship a tainted adapter. The BadNets paper demonstrated backdoored networks that performed normally on standard validation inputs but changed behavior on attacker-selected inputs, with the backdoor surviving later retraining. A green aggregate accuracy score is not an integrity check.
Why it matters
ML build systems are attractive because they combine expensive compute, long-lived storage, registry write access, cloud credentials, and automation that republishes outputs. Compromise one ingestion or conversion step and the resulting artifact may be copied across environments without another trust decision. PyTorch’s own security policy is refreshingly direct: treat untrusted models as untrusted code and isolate them.
Behavioral compromise is harder to triage than commodity malware. Conditional backdoors can remain dormant during validation, while a poisoned embedding index can preserve malicious content through every deployment built from it. NIST AI 100-2 E2025 frames poisoning and other adversarial attacks across the model lifecycle; defenders need controls at acquisition, training, evaluation, deployment, and monitoring rather than one scanner at download time.
What to do
-
Pin and verify every input. Record package hashes, container digests, source revisions, model and adapter digests, tokenizer versions, and immutable dataset snapshots in the release manifest. Reject mutable tags and branch names during promotion. Generate and verify provenance that identifies the source and build process; SLSA provenance provides the basic attestation model. Keep software, model, and data lineage in the same incident-searchable inventory.
-
Remove executable serialization from automatic ingestion. Prefer a weights-only format such as safetensors where the use case permits it; model file format security compares the options. Block pickle artifacts,
weights_only=False, remote model code, and custom operators at untrusted boundaries. Patch frameworks promptly. PyTorch 2.6.0 fixed CVE-2025-32434, but do not fossilize that version as a permanent safe floor. If conversion is unavoidable, quarantine it rather than blessing the input. -
Make ingestion disposable. Load and convert third-party artifacts in a fresh sandbox with no cloud credentials, no registry write token, read-only input, a strict output allowlist, process limits, and default-deny egress. Run as a non-root identity. Promote only the resulting inert artifact and its verified digest. Keep production registries unable to pull directly from public hubs.
-
Test provenance and behavior separately. Diff dataset manifests and label distributions, inspect training-code changes, compare candidate outputs against a known-good model, and maintain trigger-oriented tests for high-risk classes. For LLM and RAG releases, exercise adversarial retrieval, system-prompt exfiltration, and tool-call abuse. A signature check cannot catch a deliberately backdoored but correctly signed model.
-
Instrument rollback before deployment. Log the exact model, dataset, code, and container digests for every training run and serving release. Alert on unexpected child processes or network egress from loaders. Canary new artifacts, retain immutable predecessors, and monitor per-slice behavior rather than only fleet averages. Practical ML observability will not establish provenance, but it can tell responders which artifact produced the suspicious outcome.
The operating rule is simple: treat every external ML asset as hostile until its origin, bytes, loading behavior, and model behavior have each passed a separate control. Vendor badges and a green scanner icon are metadata, not absolution.


